

A well-designed data warehouse turns scattered data into fast, reliable insights. This guide covers the core principles, architectures, and design decisions behind building one, from choosing an integration approach to modeling your data for analysis.
These days, data warehouses are essential for businesses. They let companies store data from multiple sources in one place, breaking down data silos and making it easier to process and analyze. As beneficial as data warehouses are, integrating them into your infrastructure can be complicated, especially when you’re designing it.
Designing a data warehouse comes with many challenges and changing requirements. It’s an ongoing process to improve how the system extracts, loads, and transforms data from different sources, known as ETL (extract, transform, load) or, more recently, ELT (extract, load, transform). Because of this complexity, you need to consider many factors before you start building.
Key Points
- Apache Iceberg has effectively become the open table-format standard in 2026, with both Snowflake and Databricks supporting Iceberg v3 in General Availability.
- The mature 2026 design pattern combines a Data Vault 2.0 integration layer with dimensional star-schema marts, while dbt (and the new dbt Fusion engine) makes Data Vault implementations more accessible.
- The warehouse versus data lake debate is no longer an either/or decision. Snowflake, Databricks, and BigQuery all support SQL, Python, and AI workloads on architectures with separated storage and compute.
What Is Data Warehouse Design and Why Does It Matter in 2026?
Data warehouse design is the practice of structuring a central analytical repository so data from many sources can be ingested, modeled, and queried efficiently. It spans architecture (storage and compute separation, open table formats like Iceberg or Delta), integration approach (top-down Inmon or bottom-up Kimball), and modeling (star, snowflake, or galaxy schemas, increasingly paired with Data Vault 2.0 for auditable integration).
What Are the Key Components of a Data Warehouse Architecture?
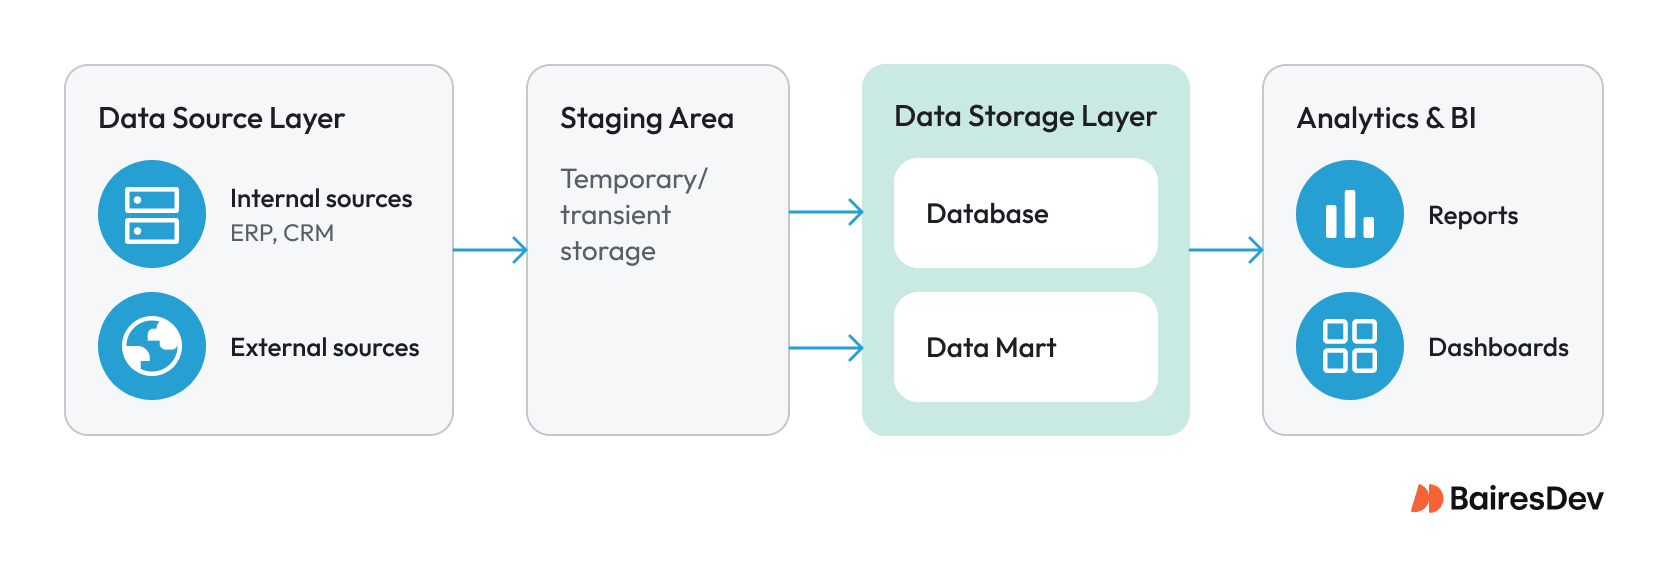
When building a data warehouse, you need to plan its architecture carefully. Understanding the key components helps you make the most of your system. Here are the main elements you should consider when designing a data warehouse:
- Data source layer: the sources from which you gather the data, including both internal (ERP, CRM, etc.) and external (social media, public databases, etc.) sources
- Staging area: the temporary storage where all the data you gather gets consolidated and checked for data quality before being stored
- Data storage layer: the database that stores your structured, historical data and the data mart that serves it up for analysis and reporting. Today, this layer is typically built on a cloud platform such as Snowflake, Databricks, or Google BigQuery, rather than an on-premises database
- Analytics and business intelligence: the data analytics and online business analytical processing tools that query, mine, and evaluate the data to build reports and visualizations
You can organize these elements using two main data warehouse design approaches, which we’ll discuss next.
Top-Down or Bottom-Up: Which Integration Approach Should You Choose?
The data source layer sends structured, semi-structured, or unstructured data to the staging area, where it’s cleaned. From there, the two approaches diverge.
Top-down approach
In the top-down approach, the clean data lands in the centralized data warehouse first, then gets divided into department specific data marts for as many functions as there are in the company.
Bottom-up approach
With this method, clean data is sent to the data marts first, then combined into the data warehouse. This approach delivers reports for specific functions faster, but the overall view across data marts may not be as consistent as in the top-down approach.
| Approach | Originator | Data flow | Best for | Trade-off |
| Top-down | Inmon | Cleaned data to central warehouse first, then derived marts | Governed enterprise consistency | Slower initial delivery |
| Bottom-up | Kimball | Function-specific data marts first, later integrated | Fast departmental reporting | Less consistent conformed dimensions |
Your choice depends on how fast you need results and how important consistency is for your business.
If your priority is a single, consistent view of data across the whole company, even if it takes longer to get there, the top-down approach is the safer choice. Since all data passes through the warehouse before reaching the data marts, you avoid the risk of marts drifting out of sync with each other.
If you need to deliver reports for a specific team or function quickly, the bottom-up approach gets you there faster, since data marts are built first. The tradeoff is that without careful planning, marts built independently can end up with inconsistent definitions of the same metrics, making it harder to combine them into a single company-wide view later.
Many organizations use both approaches. They start with bottom-up to get quick results for specific teams, then move toward a top-down structure as the warehouse grows.
Why Does Storage and Compute Separation Matter?
In traditional data warehouses, storage and compute were linked, so you had to scale both together even if you only needed more of one. Cloud platforms have changed this by letting you scale storage and compute independently.
Now, separating storage and compute is standard in new data warehouse designs. This setup lets companies store more data at a lower cost and pay for compute only when running queries, making it more efficient and flexible than older systems.
How Do Open Table Formats Like Iceberg and Delta Shape Design?
With storage and compute now separate, open table formats have become the new standard for storing data. Instead of locking data into one vendor’s format, open table formats allow different engines to read and write the same data. The two main formats are:
- Apache Iceberg: an open table format originally developed at Netflix, now widely adopted across the industry. Its latest version, Iceberg v3, is generally available on both Snowflake and Databricks, adding capabilities like deletion vectors for faster updates and deletes, row-level lineage for change data capture, and native support for semi-structured data
- Delta Lake: an open table format developed by Databricks, offering similar interoperability benefits and increasingly used alongside or in combination with Iceberg
| Apache Iceberg | Delta Lake | |
| Originator | Netflix (now Apache open source) | Databricks |
| 2026 status | Iceberg v3 in General Availability on Snowflake and Databricks | Widely used, increasingly interoperable with Iceberg |
| Key 2026 features | Deletion vectors (faster updates/deletes), row-level lineage (change data capture), native semi-structured data support | Similar interoperability benefits; often paired alongside or in combination with Iceberg |
| Best fit | Multi-engine/multi-vendor flexibility | Teams already in the Databricks ecosystem |
This change has also affected how people view data warehouses and data lakes. Warehouses were for structured data and reporting, while lakes stored raw, unstructured files. In the past, companies had to choose one or manage both separately.
Open table formats have removed the need to choose between a warehouse and a lake. Now, the ‘lakehouse’ architecture stores raw data like a lake but adds a querying layer like a warehouse. Nowadays, most cloud platforms offer lakehouse features, so the main decision is how to set up one system for both tasks.
Choosing a format isn’t just a storage decision; it carries through the rest of your design. It affects which engines and platforms can read your data without conversion, whether you can move workloads between vendors without a costly migration, and how much of the format’s newer features (like Iceberg v3’s deletion vectors and row lineage) you can actually use day-to-day. Since Iceberg and Delta both keep gaining ground, this is one of the earlier calls to get right, since it’s harder to unwind than most other design choices later on.
What Are the Steps in Designing a Data Warehouse?
While not all data warehouse design processes look the same, several steps are common to most. They’ll look different depending on the data sources, the complexity of the desired results, and the overall system complexity. However, the core steps can be summed up as follows:
Define requirements
The first step is determining the business needs, goals, and expectations surrounding the data warehousing project.
Explore and conceptualize
At this stage, the team reviews data sources and security needs, and works to understand the users. Engineers then outline the data warehouse, pick the optimal architecture, and decide how it will be deployed.
Plan
Once the draft is ready, the team defines the project’s scope, deliverables, and roadmap, considering available resources, budget, and risks.
Analyze technology and data sources in depth
Next, the engineering team looks closely at the platforms they can use to build the warehouse. Developers also analyze the data sources and plan how to extract, transform, and load the data.
Model the data
At this point, the team selects a data model for the warehouse and data marts. Common options are the star, snowflake, and galaxy schemas.
Develop the warehouse
After the project scope is defined and agreed upon, the engineering team builds the solution by connecting data sources to the databases, creating data marts, deploying ETL or ELT processes, and testing the entire system.
Deploy and maintain
Once development is complete, the team launches the solution for all users, closely monitoring performance, resolving issues as they arise, and adjusting different parts to ensure data availability, quality, and security.
What are the Best Practices for Designing a Modern Cloud Data Warehouse?
Because designing a data warehouse is complex, it’s worth keeping a set of best practices in mind. By following these, the engineering team can avoid common mistakes and streamline the entire development process.
- Properly define the data model. You always need to know what kind of data you’re gathering and how to clean and store it to ensure strong data quality for better analysis.
- Build a data flow diagram. Understanding where all your data repositories and data marts are, and how they handle information coming from your sources, can help you refine your data-based operations.
- Use a standard data warehouse architecture. Using a well-known, tested architecture can increase efficiency and give you a clearer way to maintain and upgrade the data warehouse.
- Divide your data warehouse projects into smaller pieces. Adopting an agile methodology is key when designing a data warehouse, as it lets you deliver valuable pieces of the system faster. Also, you’ll be able to evolve the system more quickly as your needs and data change.
- Automate your data warehousing. You can use multiple automation tools to clean data, enforce coding standards, and scale up and down.
- Build on a cloud platform. Most new data warehouses are built on cloud platforms like Snowflake, Databricks, or BigQuery from the start, rather than migrated to the cloud later. This gives you storage-compute separation and open table format support without having to retrofit them into an existing system.
Which Data Modeling Schema Fits Your Analytics Needs?
A schema is a logical description of the database that lists the name and description of all record types. Unlike regular databases, data warehouses don’t use the relational model. Instead, they use one of these three schemas:
#1 Star schema
A fact table is at the center of a star-like arrangement, and it’s surrounded by as many associated dimension tables as necessary.
#2 Snowflake schema
Building on top of the star schema, the snowflake schema adds additional dimension tables to each dimension table present in a star schema.
#3 Galaxy schema
In this schema, two fact tables share the same dimension tables.
In addition to schemas, many modern data warehouses also use Data Vault 2.0, a modeling method that organizes data into hubs, links, and satellites to track changes over time. Teams often use Data Vault for the raw data layer and a star schema for the layer that BI tools query. Tools like AutomateDV, a dbt package, can automate much of this ETL work and now run on dbt’s Fusion engine for faster builds.
The best schema for your warehouse depends on how your data marts are used and who is querying them.
If you want simplicity for BI tools and business users who write their own queries, the star schema is usually the best choice. Its simple structure makes joins easy and keeps reporting fast.
If storage efficiency and data integrity are more important than simple queries, such as with large dimension tables that change often, the snowflake schema helps by reducing data redundancy. However, it does make joins more complex.
If you have multiple business processes that share the same dimensions, like sales and inventory both referencing product and location data, the galaxy schema helps you avoid duplicating those dimension tables across separate models.
With the architecture, integration approach, and schema choices covered, here’s how they come together in practice, along with where to be careful.
When Should You Use a Modern Data Warehouse Architecture?
- Centralizing CRM, ERP, and product data into one governed analytical repository for cross-functional BI reporting.
- Building auditable, regulated integration layers (finance, healthcare, mobility) using Data Vault 2.0 feeding star-schema marts.
- Standardizing on an open table format so multiple engines (Snowflake, Databricks, BI tools) can query the same data without copies.
What Are Common Data Warehouse Pitfalls to Avoid?
- Don’t over-engineer a full Data Vault 2.0 integration layer for a small, single-source reporting need; a straightforward dimensional star schema is simpler and faster to deliver.
- Avoid the outdated “warehouse or data lake, pick one” framing.
- Don’t hand-build ETL when modern ELT and dbt automation handle transformations inside the warehouse more reliably.
BairesDev Helps Your Company To Create or Improve Data Warehouse Architecture
A clean integration layer is only as good as the people who model it, which is why most teams bring in data engineers who architect warehouses for multi-source analytics before committing to a schema. They can stress-test whether a top-down enterprise model or bottom-up data marts fit the reporting needs, and decide early whether Iceberg or Delta should be the open table standard.
These are exactly the kinds of decisions that are hard to unwind later, which is why designing a data warehouse is one of the most complex projects your company can undertake. That’s why you need the help from seasoned experts who can help you overcome typical pitfalls while providing you with a high-performing, robust, and scalable warehousing solution. In other words, that’s why you need BairesDev.
We have a team of elite Data Warehousing Experts that can help you ideate, conceptualize, design, and architect your solution. We have years of cross-industry experience delivering complex and scalable warehousing platforms that can redefine how you handle and manage your data. It doesn’t matter what type of data warehouse you’re trying to build: We can elevate its quality and deliver the results you’re looking for.
Key Takeaways
- Separation of storage and compute is now baseline across Snowflake, Databricks, and BigQuery, not a differentiator, so focus design decisions on table formats, governance, and modeling instead.
- Choose the integration approach deliberately: top-down (Inmon) for a single governed enterprise warehouse, bottom-up (Kimball) for fast function-specific data marts. Many teams now run a hybrid of both.
- Open table formats (Apache Iceberg, Delta Lake) and the hybrid of Data Vault 2.0 with dimensional star schemas are the defining 2026 design choices for interoperable, auditable, multi-engine analytics.